A static results page for Local Pro, a local LLM evaluation and reporting toolkit developed on a MacBook Pro.
Static benchmark results — no live inference.
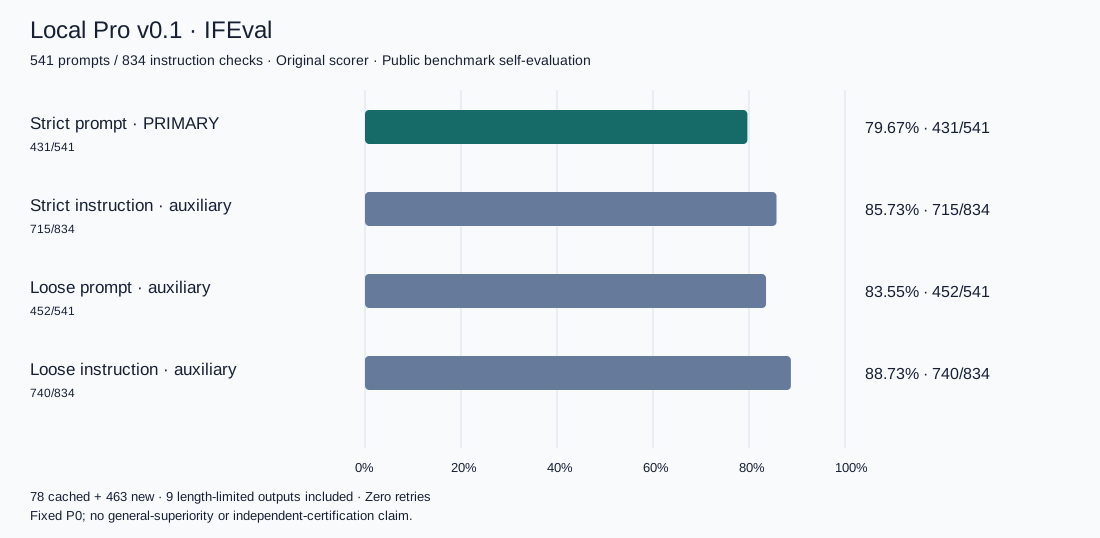
STRICT PROMPT ACCURACY
79.67%
431/541 prompts
Fixed P0 · Original IFEval scorer Public benchmark self-evaluation
01 / THE SCORECARD
One benchmark. Four views.
Prompt-level accuracy asks whether every instruction in a prompt was followed. Instruction-level accuracy counts individual requirements. These metrics are not averaged together.
P0 sends the original user message only: no extra system prompt, few-shot examples or tools.
Context / output limit
8192 / 2048 tokens
Temperature / top-p / seed
0.0 / 1.0 / 42
Thinking / passes / concurrency
False / 1 / 1
Original IFEval scorer revision e6890f85757dd84e27ca6df2dd30651dafad28e0.
Developed on MacBook Pro / Apple Silicon. All 463 new loads recorded 48 GiB RAM. The September 9, 2026 historical profile lists Apple M5 Max (18 CPU / 40 GPU cores), macOS 26.6.2; these are not fresh per-run attestations. Environment evidence ↗
Who contributed what: Qwen provides the base model; MLX-community provides the quantized conversion. Aiden built execution/evaluation integration, result tracking, reporting code and reproducibility documentation, with Codex development assistance. No new foundation-model training is claimed; the exact upstream conversion commit remains unverified.
03 / HISTORICAL CONTEXT
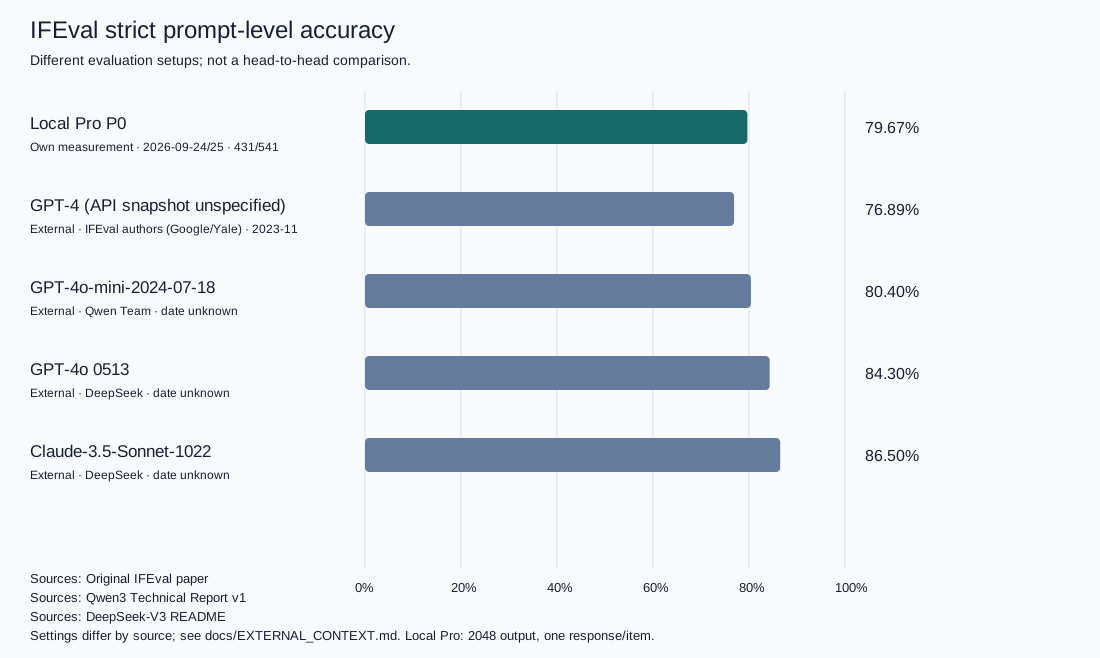
Reference points, not a ranking.
Different evaluation setups; not a head-to-head comparison.
English IFEval strict prompt-level accuracy. Historical, nearby and higher published values are shown together. External values were reported by their listed sources, not measured by Local Pro.
Output budgets, sampling and evaluation dates differ. No statistical significance, general superiority, frontier equivalence or Hugging Face certification is claimed. Detailed source conditions ↗
04 / REPRODUCIBILITY & RIGHTS
What this page does—and does not do.
Available in the public code
Rebuild reports and graphs from stored verdicts, using Python's standard library. This page is generated from a small fixed scorecard; it makes no runtime API calls.
Outside this Space
Full raw-response rescoring needs excluded raw outputs and evaluation assets. New inference needs a separate execution core and valid authority. Neither is available here. Fresh-machine generation is untested.
Public, development-exposed benchmark self-evaluation—not hidden testing, third-party certification or proof of general performance superiority.
Original Local Pro code, this static page and associated documentation: MIT License, Copyright (c) 2026 Aiden Oh. Third-party components retain their licenses; see notices. No vendor scorer, model weights, tokenizer, prompts, raw outputs or private ledgers are bundled in this Space.